Matchmaking Simulator
1. Overview
PGOS provides a simulator to verify rulesets before they go online. It replays a Fake Player Dataset through the same matchmaking logic the live service uses: the same ruleset scheduling, the same searching timeout and the same rule expansions. Then it reports how every ticket ended up.
The matchmaking simulator does the following jobs:
- Replay a dataset against one or more rulesets, with configurable ticket arrival and player latency.
- Summarize the result: match rate, battles, where every ticket ended up, and why the unmatched tickets failed.
- Export the result as a
csvfile, one row per player, for developers to do data post-processing tasks.
By using the matchmaking simulator, developers can know the tendencies of the rulesets they write: what kinds of matchmaking tickets will be matched quickly, and what kinds of tickets will time out due to the difficulty in finding close tickets to them.
Click Tutorial on the Matchmaking Simulator page for a step-by-step walkthrough of the minimal workflow.
2. Create a Simulation Case
Click Add Simulator Case and fill in the dialog:
| Field | Description |
|---|---|
| Match Config | Optional. Picking one selects its rulesets and fills in its searching timeout. The simulator runs rulesets, not match configs, so this only saves you from lining them up by hand. |
| Ruleset(s) | Required. One or multiple rulesets. When multiple rulesets are chosen, they must declare the same player attributes, and the simulator follows the strategy of Multiple Rulesets, the same as online matchmaking. |
| Fake Player Dataset | Required. Only datasets that contain every player attribute declared by the chosen rulesets can be selected. |
| Ticket Arrival | How tickets enter the pool. See Ticket Arrival. |
| Latency Source | Where player latency comes from. See Latency Source. |
| Searching Timeout | How long a ticket may stay in the pool. It is shared by every ticket, the same as the searching timeout of a Match Config. Auto uses the max waitTimeSeconds in the expansions of the ruleset plus 30 seconds. |
| Simulated Duration | How long to simulate. Auto uses the arrival time of the last ticket plus the searching timeout. The simulation runs in real time, so this is also roughly how long the case takes. |
2.1 Ticket Arrival
| Option | Behavior |
|---|---|
| From dataset | Default. Replays the enter_offset_ms column of the dataset, so tickets enter the pool the way they did in production. |
| Fake | Ignores enter_offset_ms and generates arrival times with the settings below, assigned in dataset row order. |
| All at once | Every ticket enters the pool at the same time. Useful for comparing a burst with a gradual arrival on the same dataset. |
When Fake is selected, choose a distribution:
- Uniform: spreads tickets randomly across the Arrival Span (seconds from the first ticket to the last).
- Poisson: exponential gaps at the given Arrival Rate (tickets per second). It is the closest to live traffic.
- Constant: equal gaps at the given Arrival Rate.
A party ticket counts once in the arrival rate, however many players it holds. The same dataset and parameters always produce the same arrival times, so reruns stay comparable. The dialog also estimates how long it takes for all tickets to arrive.
- If the dataset has no non-zero
enter_offset_ms, From dataset admits every ticket at the same moment, the same as All at once. Choose Fake to spread the arrivals. The dialog shows a hint in this case. - A running case stops after 1 hour by default. Tickets that would arrive later never enter the pool, so shorten the span or raise the rate for large datasets.
2.2 Latency Source
| Option | Behavior |
|---|---|
| From dataset | Default. Uses the latency.<region> columns of the dataset, so two runs see the same input. |
| Fake | Ignores the latency columns of the dataset. Every player gets one latency per region from the distributions you set. |
| None | No latency at all, which is what a client that never reported a speed test looks like. |
When Fake is selected, add one row per region (up to 16) and set its distribution in milliseconds:
- Normal: Mean and Std dev, cut to [Min, Max].
- Uniform: spread evenly across [Min, Max].
Region names may only contain letters, digits, _, . and -. The generated latencies are fixed for a case: a rerun with the same settings gives every player the same values.
- A
latencyRuleonly passes when every player in a proposal has latency for a shared region. If the dataset has nolatency.<region>columns, From dataset and None make everylatencyRulefail, so rulesets that use it match nothing. The dialog warns about this after you pick such a dataset. - With Fake, whether
latencyRulepasses depends on the distributions you set and themaxLatency/maxDistanceof the rule. Do not draw conclusions about real latency from a Fake run.
3. Queue and Lifecycle
Simulation cases are queued and run by the simulator service. Each server instance runs one case at a time, and multiple instances run cases in parallel. The indicator at the top right of the list shows how many cases are running and waiting across all title regions. It is hidden when the queue is idle. A queued case also shows how many cases are ahead of it.
| Status | Meaning |
|---|---|
| Queued | Waiting for a free server instance. |
| Running | Being simulated. The result column shows a progress bar. |
| Completed | Finished. Check the end reason below to see whether the result is complete. |
| Cancelled | Cancelled by a user. |
| Aborted | Failed because of a system error, for example the dataset could not be loaded. |
| Terminated | The server instance running the case stopped unexpectedly, and the case was reclaimed. |
Every case that finishes with a result shows one of the following end reasons:
- Pool drained: every ticket concluded, so the match rate is complete.
- Reached the simulated duration: some tickets were still in the pool when the simulation ended. Mind the denominator.
- Aborted: wall clock budget exceeded: the case ran for more than 1 hour and was stopped. The result is incomplete, so do not draw conclusions from it.
- Cancelled while running: only part of the traffic was replayed, so the match rate is not comparable.
Use the Operation column of the list to manage cases:
- Cancel removes a queued case from the queue, or stops a running case. A stopped case keeps its partial result.
- Rerun opens the dialog with the settings of the case filled in.
- Download CSV exports the result. See Data Post Processing.
4. Inspect Simulation Result
4.1 Create a Demo Ruleset
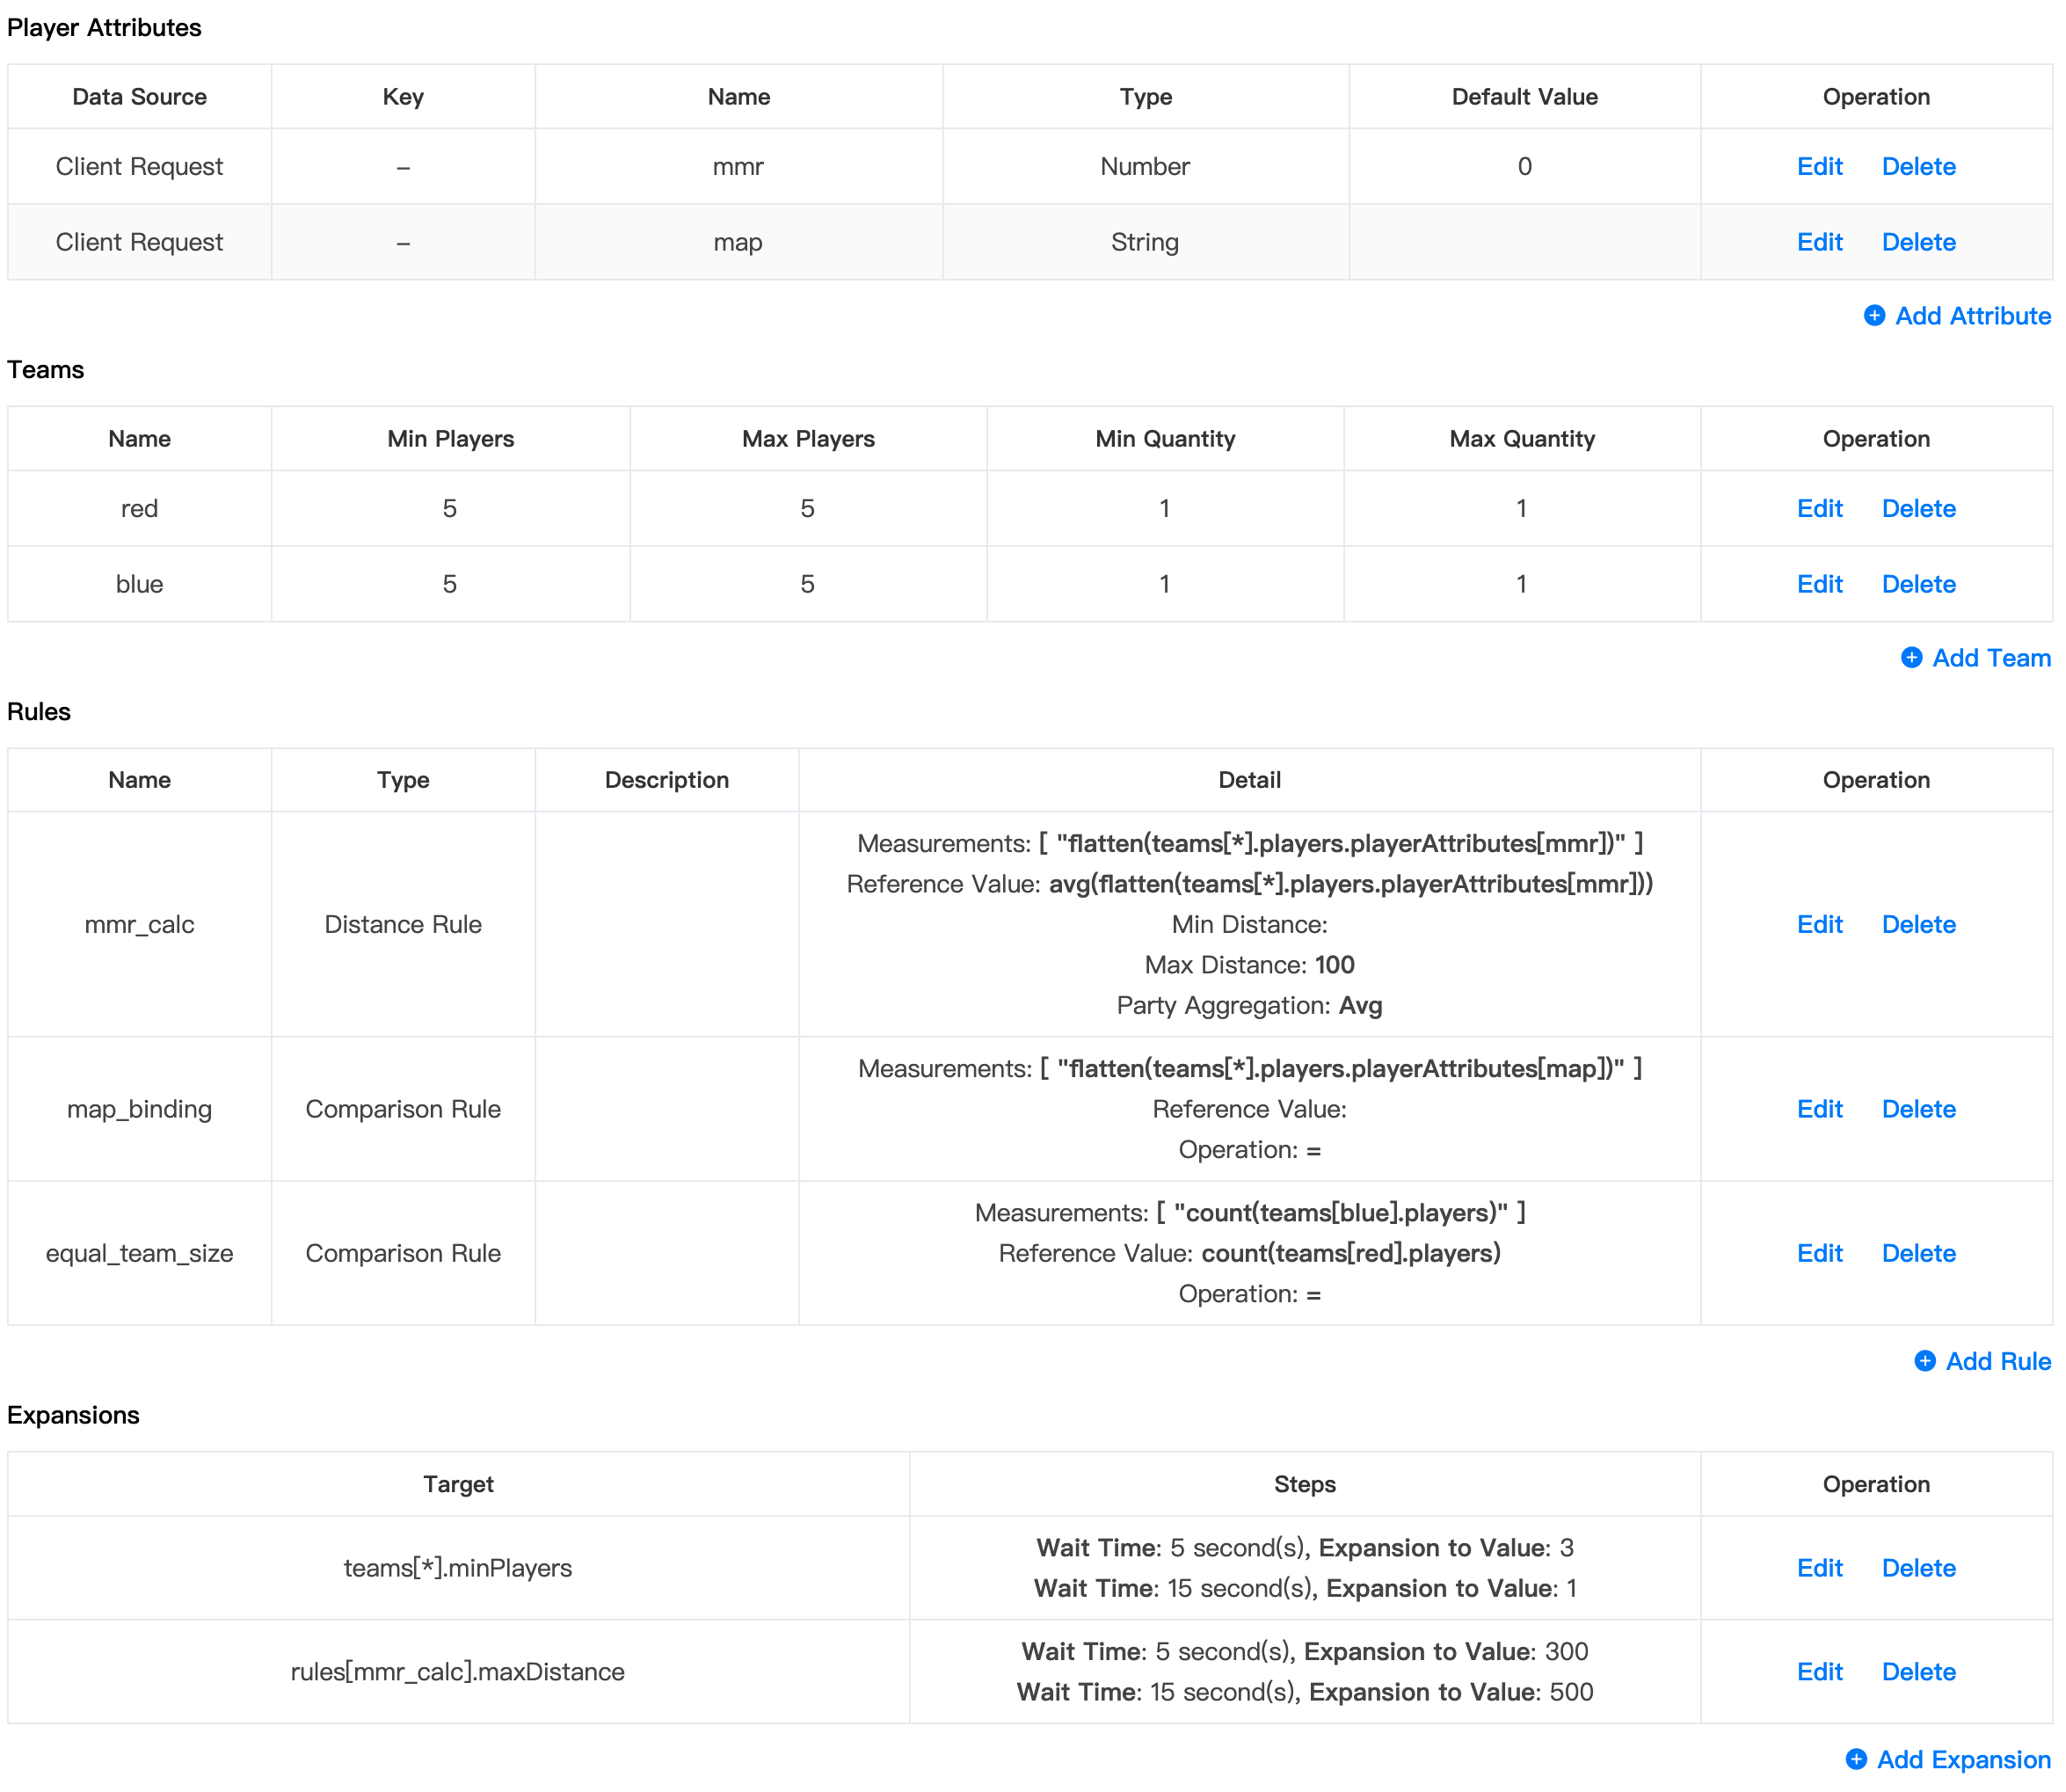
Let's take this 5v5 ruleset as an example:
- Two attributes:
mmrandmapare defined. - Two teams, 5v5 by default, relaxed to 1v1 if no tickets are matched after 15 seconds.
- A distance rule that refers to the
mmrof players in a battle, which limits the max distance of themmrto 100, and is relaxed to 500 after 15 seconds. - A comparison rule that refers
map, which will group players who chooses the samemapin a battle. - A comparison rule that uses the
countfunction to ensure two teams have the same number of players.
4.2 Create a Fake Player Dataset
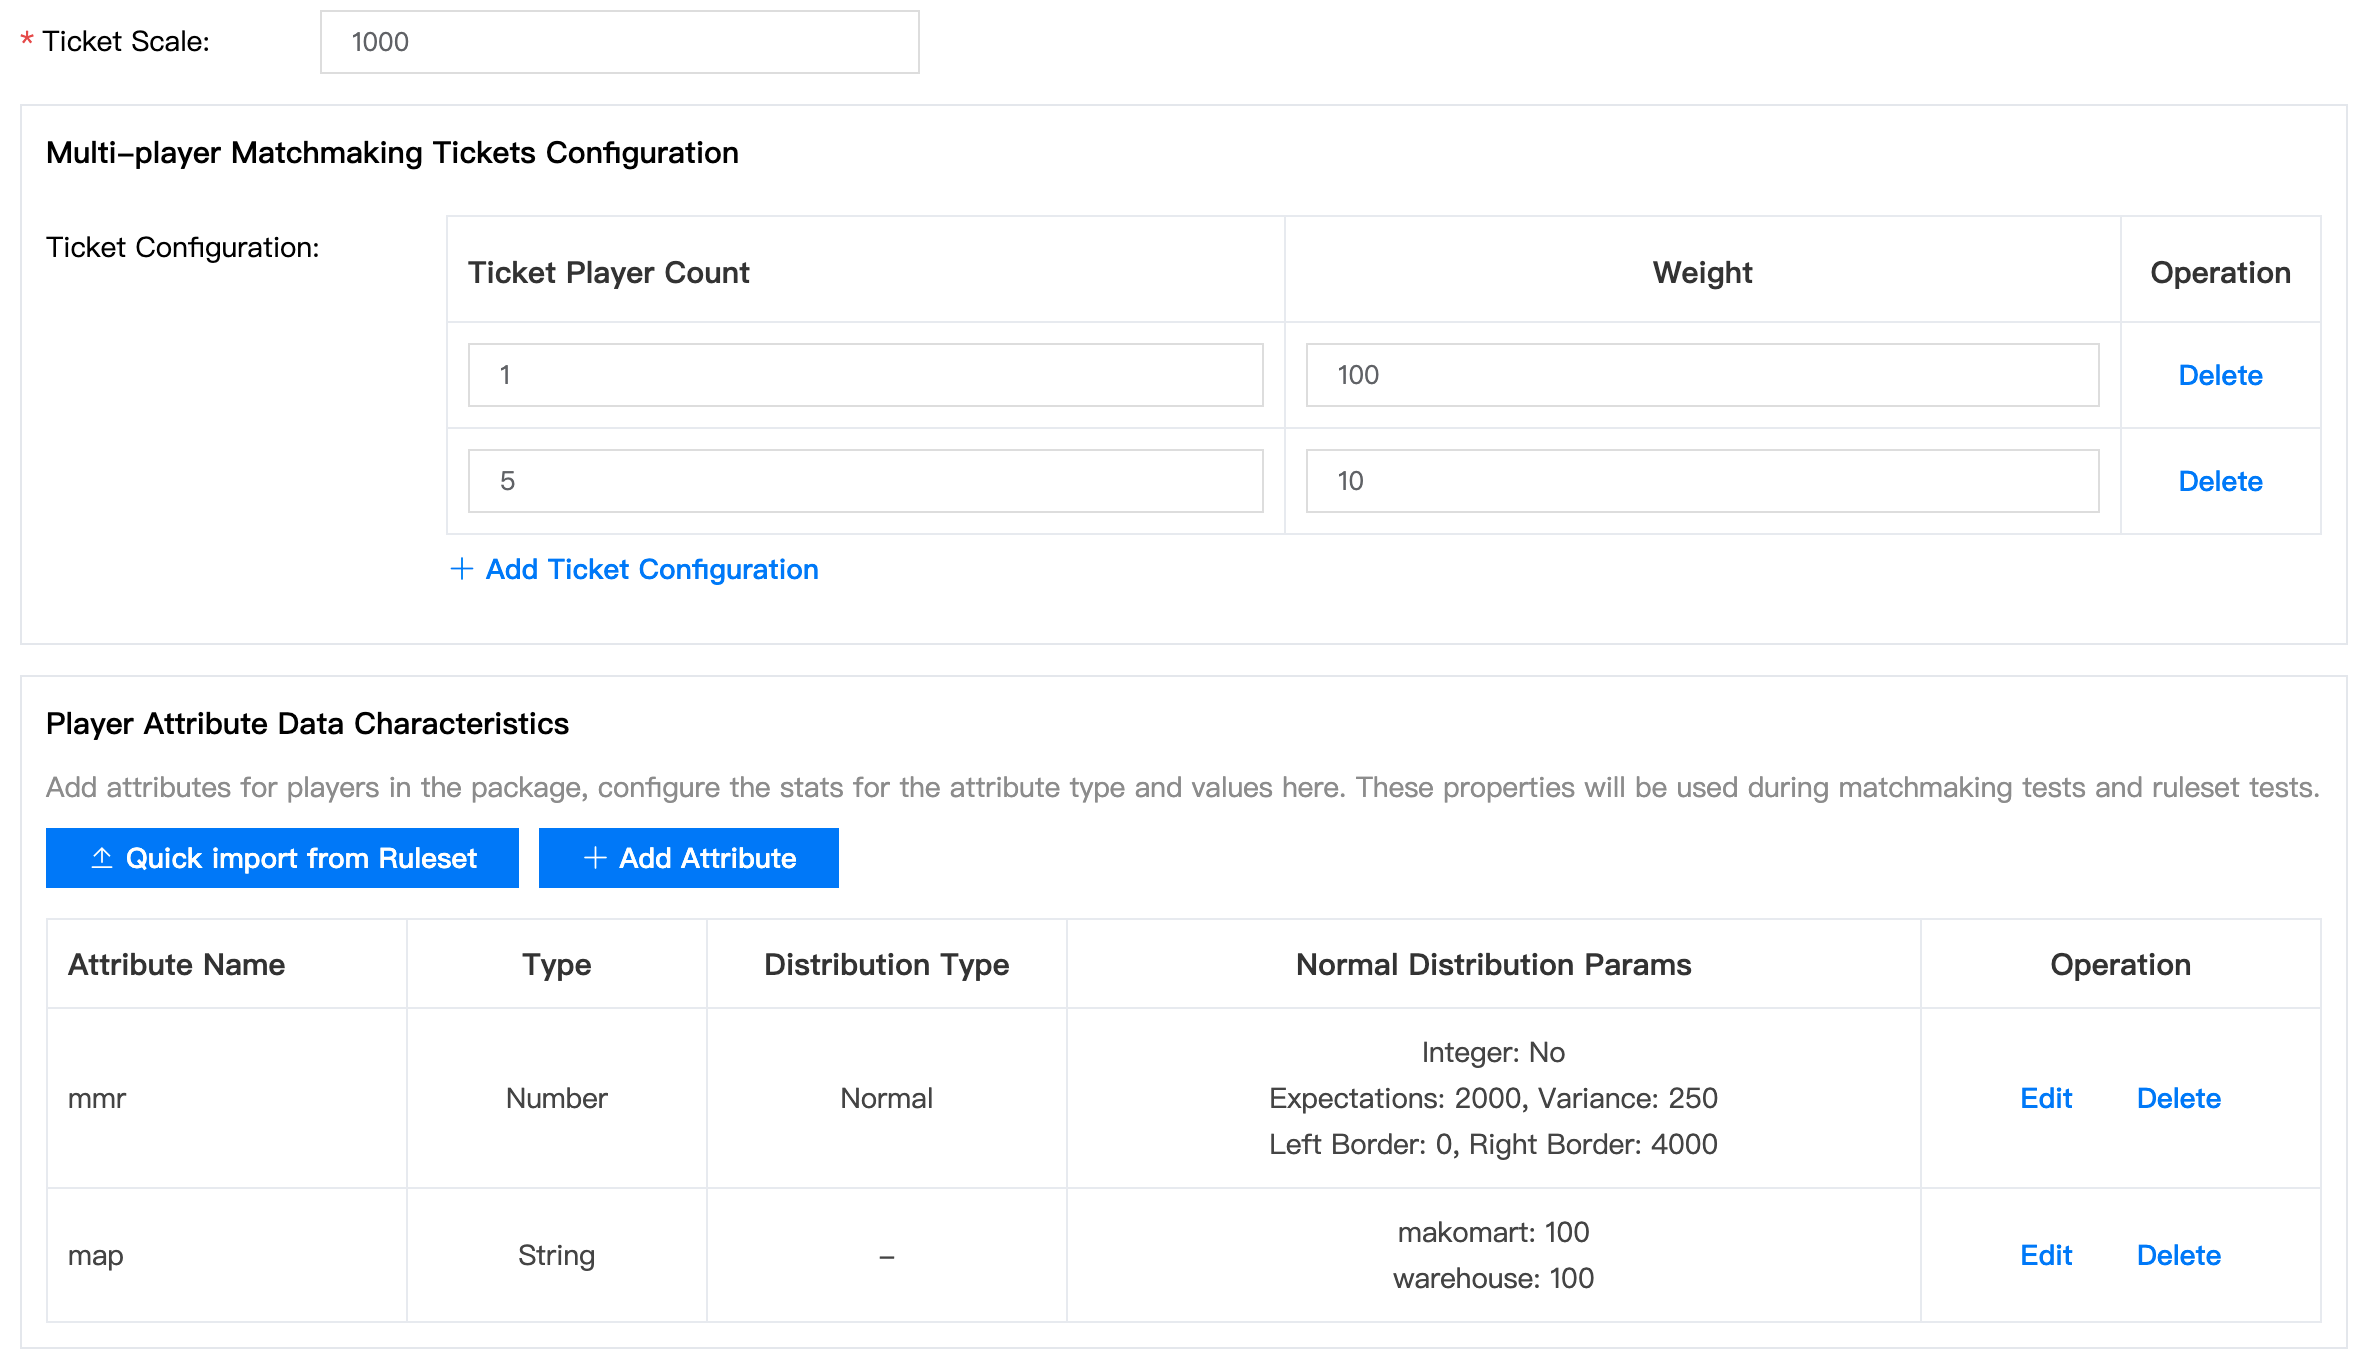
Next, we create a fake player dataset that contains 1000 matchmaking tickets:
- Let's mix some solo tickets with 5-player tickets, and make the ratio to be 100:10
- Quickly import attribute definitions from ruleset
mmrcommonly meets normal distribution, let's makeavgto be 2000 andstddevto be 250, so that some tickets will have to wait for the rules to be expanded to find matched tickets : )maphas two enums: makomart and warehouse, the ratio is 100:100
4.3 Fire the Simulation
Now we create a simulation case using the ruleset and fake player dataset above. One or multiple rulesets can be selected for simulation. When multiple rulesets are chosen, the simulator will follow the strategy of Multiple Rulesets to run. The other fields can stay at their defaults.
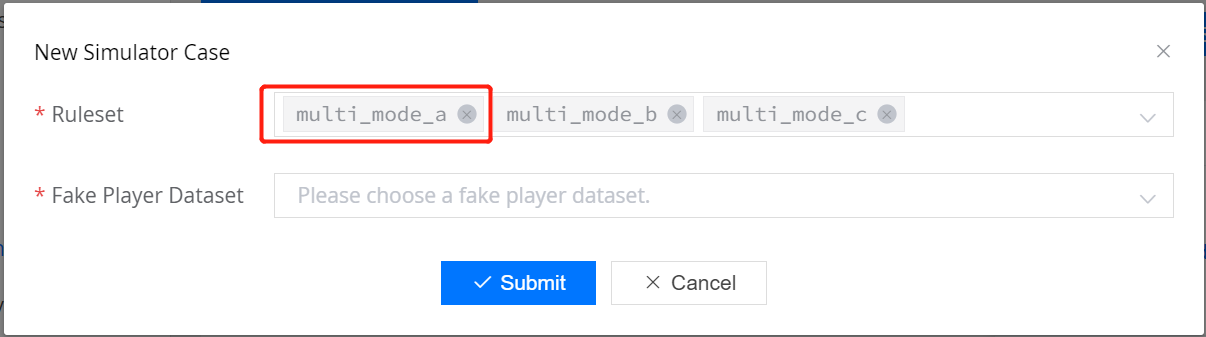
The case enters the queue first, and turns to Running once a server instance is free.
4.4 Read the Result
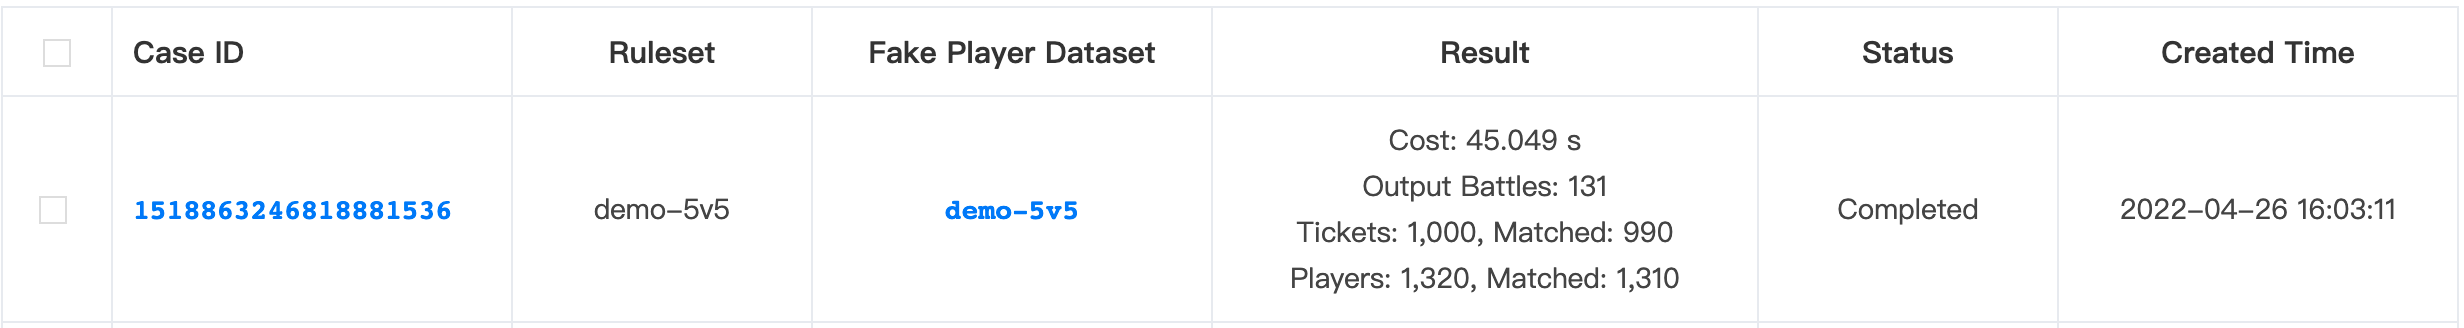
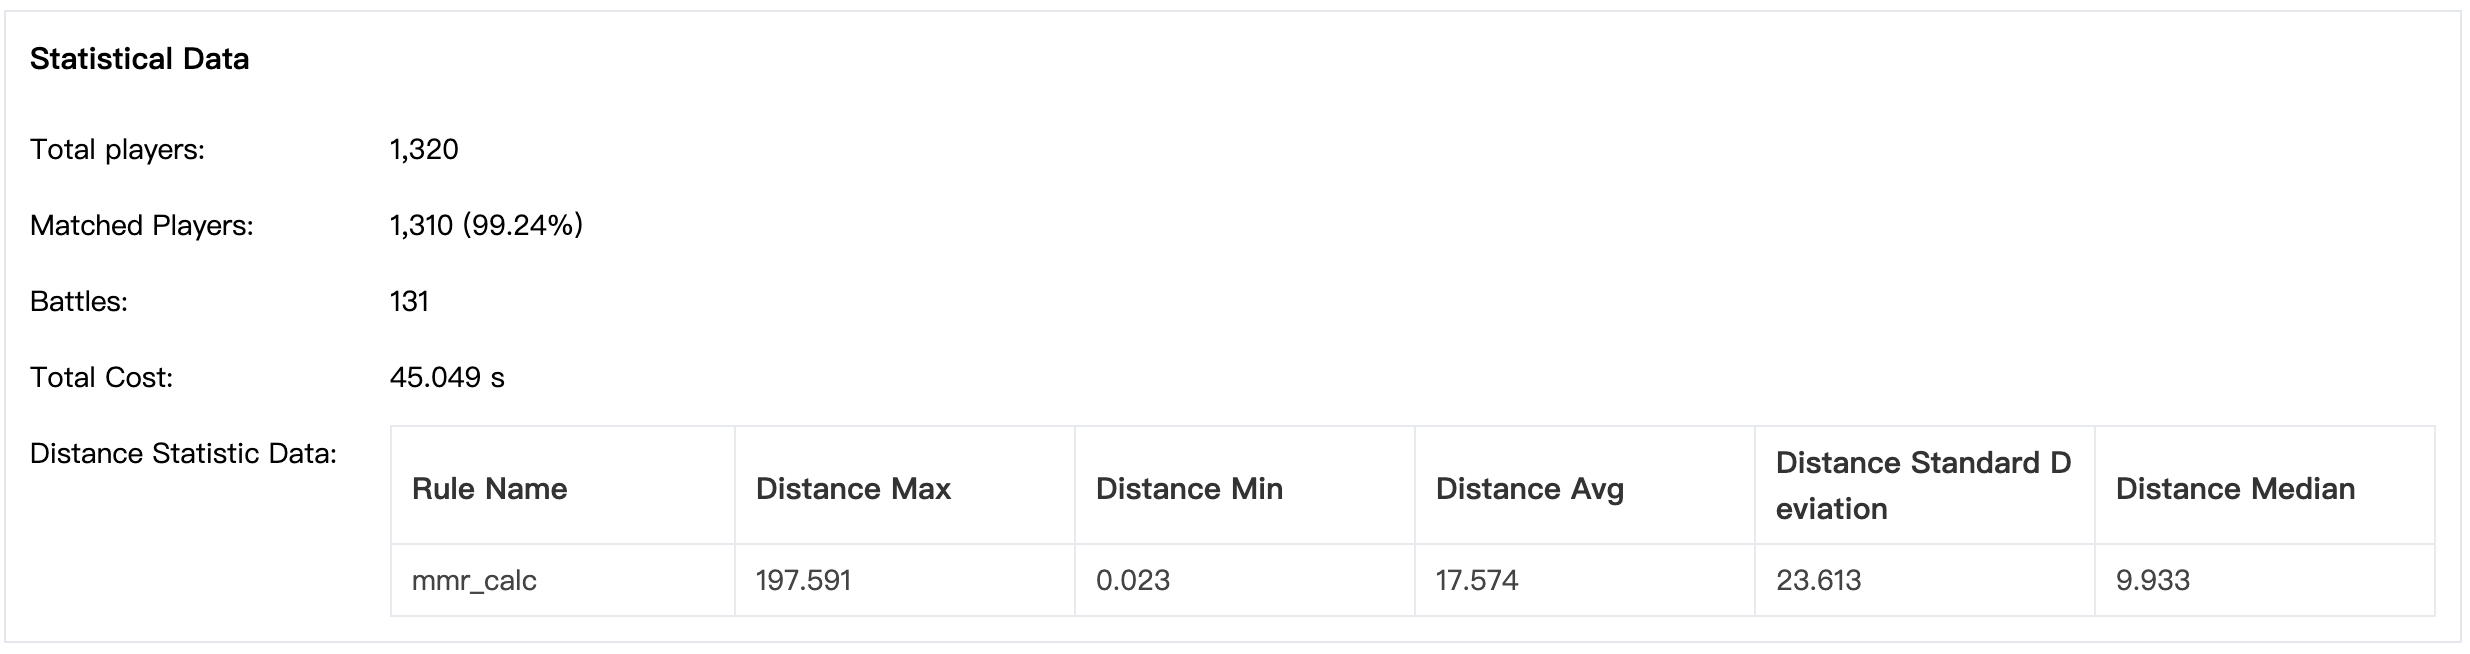
When the case is finished, the list shows its match rate and ticket outcome. Click Details to open the result page:
- Case information: the rulesets (with a snapshot of each script), the dataset, the arrival and latency settings, the searching timeout, the duration limit and the execution mode that was actually used. Copy Summary copies all of it together with the key numbers, which is handy for sharing.
- Statistical Data: match rate, battles, players matched and duration, followed by the ticket outcome: matched, timed out, or left in the pool when the simulation ended. When multiple rulesets are simulated, a chart shows how many matches each ruleset formed.
- Simulator metrics: curves over the simulated time, including tickets starting and finishing per second, the pool backlog and the wait of matched tickets.
- Why unmatched: click an outcome or a chart bar to list the tickets behind it. It also shows the distribution of wait time, the expansion step at which tickets were matched, the size of matched battles, and a warning when players have no latency data.
- Raw summary: the plain-text summary written by the simulator, collapsed by default.
These diagnostics help developers evaluate the effect of each rule, for example whether a distance rule is too strict before its expansion takes effect.
5. Data Post Processing
The matchmaking result can be exported as a csv file, one row per player. Tickets that were not matched are included, so the file covers the whole dataset.
The first eleven columns are predefined, followed by one latency.<region> column per region that has latency data, and then one column per player attribute.
| Column | Meaning |
|---|---|
ruleset_name | The ruleset the battle was formed with. Empty if the ticket was not matched. |
player_id | The player. |
ticket_id | The ticket the player belongs to. Players of a party ticket share it. |
battle_id | The battle the ticket was matched into. Empty if the ticket was not matched. |
team | The team the player was put into. Empty if the ticket was not matched. |
status | COMPLETED (matched), TIMEDOUT (reached the searching timeout), or LEFT (still in the pool when the simulation ended). |
enter_offset_ms | When the ticket entered the pool, in milliseconds after the simulation started. |
concluded_at_ms | When the ticket was matched or timed out, in milliseconds after the simulation started. |
wait_ms | How long the ticket waited in the pool, in milliseconds. |
anchor_count | How many times the ticket was picked as the first ticket of a candidate match. |
reput_count | How many times the ticket was put back into the pool after a failed attempt. |
latency.<region> | The latency of the player to the region, in milliseconds. An empty cell means no latency for that region, which is different from 0. |
ruleset_name,player_id,ticket_id,battle_id,team,status,enter_offset_ms,concluded_at_ms,wait_ms,anchor_count,reput_count,latency.Z1,latency.Z2,mmr,map
demo-5v5,player-713,ticket-545,3fe58d15-9193-41ad-9eba-545e3dc9e4bd,red,COMPLETED,899,1000,101,0,1,44,56,1786.863027,warehouse
demo-5v5,player-714,ticket-545,3fe58d15-9193-41ad-9eba-545e3dc9e4bd,red,COMPLETED,899,1000,101,0,1,45,57,2241.119114,warehouse
demo-5v5,player-116,ticket-84,3fe58d15-9193-41ad-9eba-545e3dc9e4bd,blue,COMPLETED,912,1000,88,0,0,61,39,1920.060106,warehouse
demo-5v5,player-711,ticket-543,a16ad3d0-dff1-4aae-8e5a-47826e1ad2d2,red,COMPLETED,15420,16000,580,1,3,52,70,1523.588655,makomart
,player-1301,ticket-990,,,TIMEDOUT,20242,50242,30000,6,62,,,2961.210000,makomart
...
Cases created before this format keep the columns they were created with (reput_count and elapsed_ms, without status and the time columns).
reput_count is an internal parameter in the matchmaking system. In order to expose as many details inside the black box as possible to help developers understand the ruleset they write, reput_count is exported.
In a matchmaking system, tickets are kept in a ticket pool for the matchmaker to retrieve on demand to find matches. The matchmaker pops out the ticket with the lowest reput_count as the first ticket in an empty match, and then tries to fill the remaining slots by using the filters figured out with the deduction result of the rules. If no matches are found, finally, the reput_count of these tickets is increased and put back in the ticket pool, and waits for the next try.
So the easy-to-match tickets will have relatively low reput_count and vice versa. And some of the timedout tickets will have a zero value of reput_count. Normally, most of the tickets will have a 0~5 reput_count range, and the average value is below 1.
There are two recommended methods to deal with a high reput_count situation:
- Relax the limitations of rules step by step to lower the difficulty of finding qualified matches.
- Create a ruleset by modes to let different targeted players use different rulesets.
wait_ms is the time a ticket spent in the pool before it was matched or timed out. A histogram of wait_ms shows the time node at which tickets are not matched until a ruleset expansion happens, which helps balance the efficiency and precision of a ruleset.
enter_offset_ms and concluded_at_ms place every ticket on the simulated timeline, so you can see how the backlog grows and drains over time. The simulation runs in real time, and ticket ages drift slightly with machine load, so compare runs with each other rather than reading exact milliseconds.
By utilizing the CSV data, developers can:
- Create histograms of matchmaking costs and player attribute distributions.
- Do research on clustering algorithms based on matchmaking data.
- Optimize ruleset design by reducing the overall time costs.
Contact us if you have any advice on using the matchmaking simulator.